 AI CEO Lab
YouTube Outliers: How to Find Videos That Beat Their Own Channel
An outlier is a video's views divided by its own channel's median. Here's the exact calculation, 3 ways to turn a winner into your own title, and the test for whether it travels to your niche.
Say a channel normally gets 2,000 views a video. Then one does 200,000. That's a 100x outlier: the video did the work, not the audience. MKBHD, when I scanned it on 9 September 2026, had nothing above 1.9x in its last 30 uploads.
The term spread from the strategists around MrBeast, and now the whole creator economy uses it; Viewstats built a product around it. But almost nobody states the maths. Tutorials say "previous videos" or "anything else on their channel": mean, median and eyeball, all under one word.
This guide commits to a number, then does the half everyone skips: turning an outlier into a title of your own, and checking whether it transfers at all. It's for anyone picking YouTube topics. On Instagram, the same division drives competitor analysis. The score tells you what worked. The remix tells you what to make.
The mental model
Sort by views. Copy what the biggest channels did. Take the multiple a tool prints on the screen as the answer.
Divide each video's views by its own channel's median, over a window you state. Then ask what they did differently, whether it transfers, and which remix direction fits you.
| Term | What it means |
|---|---|
| Baseline | Median views of the channel's last 15 long-form uploads. Median, with Shorts excluded, or the number is fiction. |
| Score | Views divided by the baseline. |
| Portability | Whether a format travels across niches or only works inside its own. |
| Watchlist | The channels that produced outliers, rescanned, with anything above 3x surfaced. |
If everyone remixes, is anything original?
This is a system for making versions of other people's videos. Am I adding to the pile of derivative content that made me want to quit YouTube?
Fair charge. Most videos are already remixes of remixes. Naming it lets you do it on purpose, as long as you hold a line.
- Take the structure, never the sentences. If a phrase from their title survives into yours, you copied.
- Translation and vertical remixes are the original part. Both need something that's yours: knowledge of the destination, or a stake you earned.
- A score everyone sees isn't an edge. Your own baseline over your own window is. Add the business filter and the list shrinks to one nobody else has.
The limit: this measures the past, and the number hides the moment. That's why recency and portability are in the method. Skip them and you get a precise tool for making last year's video.
Score it, then act on it
1. Get real numbers before you form an opinion
Never estimate views or medians. 2 calls to the Scrape Creators API do the job: search returns candidates with views, channel ids and dates; channel-videos returns 30 uploads with viewCountInt, lengthSeconds, publishedTime, a separate shorts array and a continuationToken. It takes handle=@name or channelId=UC....
Keep the key in an environment variable, sent as a header. If a channel won't fetch, mark the score unknown.
In Claude Code, save the skill below and say "find outliers about [topic]". In ChatGPT, upload the JSON to a Project, or give a custom GPT the stub below as an Action with an x-api-key header.
export SCRAPECREATORS_API_KEY=...   # env only, never in a prompt
H="x-api-key: $SCRAPECREATORS_API_KEY"

curl -s -H "$H" "https://api.scrapecreators.com/v1/youtube/search?query=outlier%20videos" > search.json
curl -s -H "$H" "https://api.scrapecreators.com/v1/youtube/channel-videos?handle=@mkbhd" > channel.json

# sanity check both before you trust anything downstream
python3 -c "import json;d=json.load(open('search.json'));print(d['success'], len(d['videos']))"
python3 -c "import json;d=json.load(open('channel.json'));print(len(d['videos']),'uploads,',len(d.get('shorts') or []),'shorts')"

# ChatGPT custom GPT Action (OpenAPI stub)
openapi: 3.1.0
info: {title: ScrapeCreators YouTube, version: '1'}
servers: [{url: https://api.scrapecreators.com/v1}]
paths:
  /youtube/search:
    get:
      operationId: searchYouTube
      parameters:
        - {name: query, in: query, required: true, schema: {type: string}}
  /youtube/channel-videos:
    get:
      operationId: channelVideos
      parameters:
        - {name: handle, in: query, schema: {type: string}}
        - {name: channelId, in: query, schema: {type: string}}
2. Search the topic 3 ways
Search the literal topic, the outcome phrasing ("how I", "that worked"), and the beginner phrasing ("for beginners", "explained"). Collect 30 to 60 candidates with title, channel, channel id, views, date and length.
Why: winners are titled the way the audience talks, not the way you think about your subject. Searching by hand? Use a private window. Signed in, YouTube ranks channels you already watch, and the incumbents look stronger than they are.
3. Compute the baseline, without Shorts
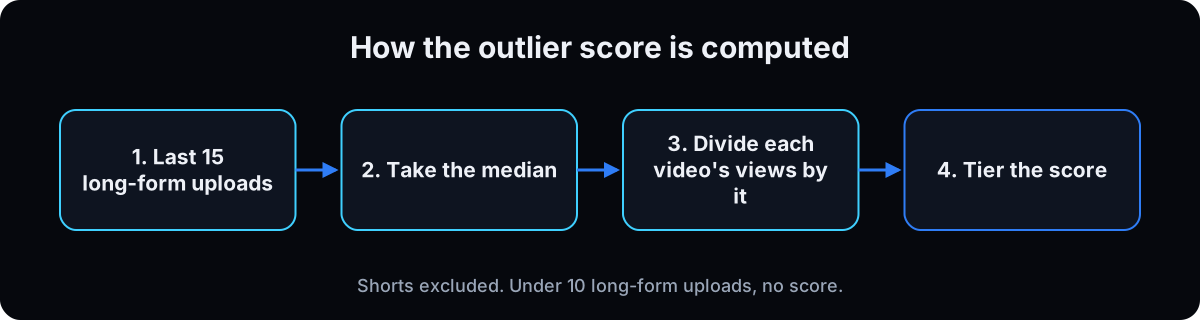 For each channel, take the median views of its last 15 long-form uploads.
Median, not mean: one viral video poisons a mean, so the channel most worth studying looks like it never has outliers.
Long-form only: a Short and a 12-minute video are different products. Filter on length, or use the separate shorts array.
15 uploads: any window is a choice, so state yours. 15 is recent without letting one bad week move it.
If a channel returns fewer than 10 long-form uploads, don't score against it. The script below refuses.
cat > outlier.py <<'PY'
import json, os, statistics as st, sys, urllib.request
KEY = os.environ["SCRAPECREATORS_API_KEY"]
handle = sys.argv[1]
req = urllib.request.Request(
    f"https://api.scrapecreators.com/v1/youtube/channel-videos?handle={handle}",
    headers={"x-api-key": KEY})
d = json.load(urllib.request.urlopen(req))
vids = [v for v in d.get("videos", []) if v.get("lengthSeconds", 0) >= 90]
if len(vids) < 10:
    sys.exit(f"only {len(vids)} long-form uploads returned; median not trustworthy")
base = vids[:15]
median = st.median(v["viewCountInt"] for v in base)
print(f"{handle}: median of last {len(base)} long-form uploads = {median:,.0f}\n")
for v in sorted(vids, key=lambda v: v["viewCountInt"], reverse=True)[:8]:
    print(f'{v["viewCountInt"]/median:6.2f}x  {v["viewCountInt"]:>10,}  {v["publishedTime"][:10]}  {v["title"][:52]}')
PY

python3 outlier.py @mkbhd
# printed on 9 Sep 2026; live counts drift, the shape does not
# @mkbhd: median of last 15 long-form uploads = 3,641,496
#   1.86x   6,781,356  2026-04-09  So This is Peak Foldable
#   1.76x   6,419,454  2026-08-09  iOS 27 Hands-On: Top 5 New Features!
#   1.66x   6,046,311  2026-04-09  Macbook Neo Review: Better than you Think!

python3 outlier.py @Viewstats
# only 2 long-form uploads returned; median not trustworthy
4. Tier it, and check it's still alive
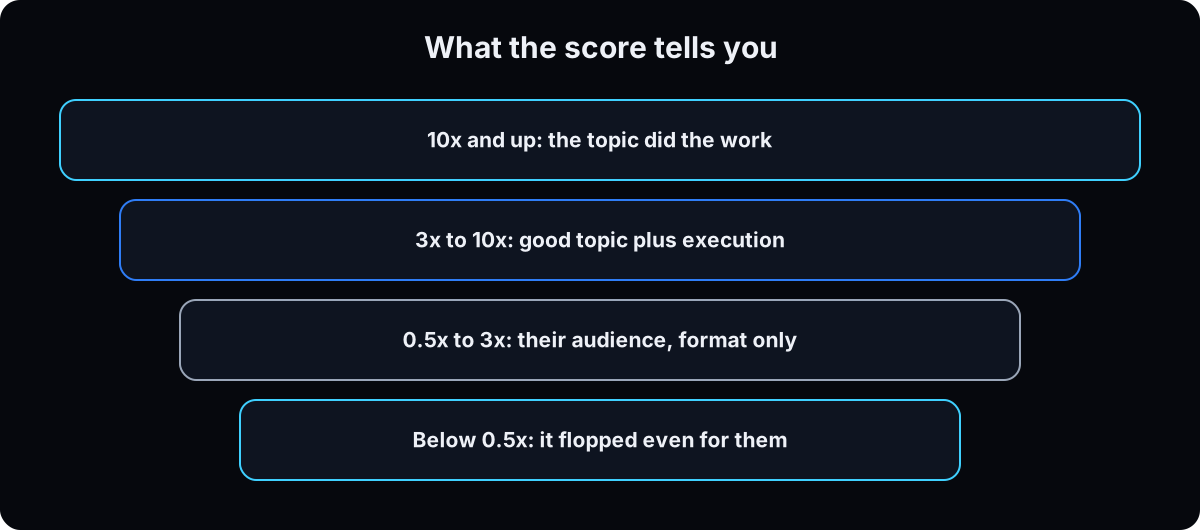 10x and up: the topic did the work. 3x to 10x: good topic plus execution. 0.5x to 3x: their audience, useful for format only. Below 0.5x: it flopped even for them; note why.
Check recency. A video can have big numbers and have stopped growing years ago. Copy it and you inherit a dead topic. Prefer outliers from the last 12 months.
MKBHD topping out at 1.86x is a correct answer: the outliers are elsewhere. Boring is a finding.
5. Ask what they did differently
Chucky, who runs titles, thumbnails and ideas for MrBeast, asks one question: what did they do differently that set this video apart? Not what it's about.
Show the top 15 with views, score and median side by side, so a 30x from a small channel stands out next to a 2x from a big one. For the top 10, note title construction, thumbnail concept (see thumbnails with ChatGPT), length and first spoken line (see writing hooks).
The number in a title sets audience size, a point from the same Viewstats walkthrough. "$10,000 a month" beats "$100,000 a month" for a cold audience because the barrier is lower. Higher numbers win with people who already believe you.
Then name the shared pattern in 2 sentences.
6. Decide whether it travels
Universal outliers work in any niche. A $1 video works in food, tech, travel and fitness, which is why it goes big. Niche-native outliers work because of the niche, like some gaming or beauty formats.
The test: strip out the subject. Is the structure still interesting? If not, it won't travel, and transplanting it will make you blame the method.
For a clinic, also ask: does this reach someone who could book? A 50x outlier on a problem your buyer doesn't have is a well-measured waste of a week.
7. Remix it 3 ways, then pick one
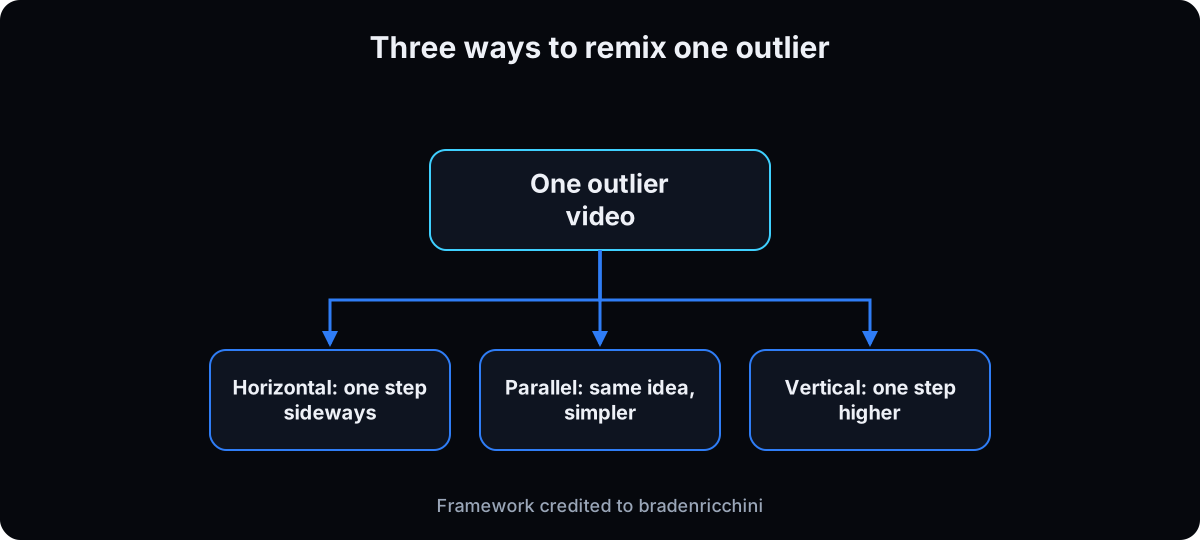 This framework is bradenricchini's. Write all 3 before choosing.
Horizontal, one step sideways: "I sent 1 million cold emails, here's what you need to know" becomes "I sent 1,000 cold emails a day for 30 days".
Parallel, the same idea simpler: "How I sent a million cold emails."
Vertical, one step higher: "How much money I made from sending 1 million cold emails." It performs best but needs credibility, or it reads as a claim.
Translate, don't transplant. "How I'd make $10,000 a month if I had to start again" in gaming becomes "how I'd get grandmaster if I started from bronze". The further you translate, the better it does.
Write the title and thumbnail concept before you film. If you can't, kill the idea.
8. Save it by video id
Save every candidate keyed by video id, with topic, score, channel median, date and portability label. Mine is a table.
Why: a second scan reads the library first and only searches for what's new. Otherwise month 2 is month 1 again, with worse morale.
9. Watch the channels behind the winners
Pick the 5 to 10 channels behind your outliers. On a schedule, pull their uploads, rescore, and surface anything above 3x. Now ideas find you.
No API key? With the gstack browser, use the browse binary directly, not /scrape, which is one-shot per call and stalls on multi-channel scans. chain runs multi-step jobs, and snapshot -D diffs a page against last time.
# gstack browse, --help confirmed
B=~/.claude/skills/gstack/browse/dist/browse

$B --help | grep 'Multi-step'
#   Multi-step:  chain (reads JSON from stdin)

# watchlist without an API key: snapshot a uploads page, then diff it next week
$B goto "https://www.youtube.com/@somechannel/videos"
$B snapshot -D          # -D/--diff: diff against previous snapshot
Starter prompts
Paste these as written. They are short on purpose, because the long ones drift.
Here is an outlier: title [title], views [N], channel median [M], score [Nx]. First tell me whether it is universal or niche-native, and why in one line. If it is universal, write three versions of it for [my topic] and [my one person]: 1) HORIZONTAL: one step sideways. Same shape, different scale or angle. 2) PARALLEL: the same idea, restated with fewer words and a smaller promise. 3) VERTICAL: one step higher. Add a stake, a number or an outcome, and tell me what credibility I would need for it to land. Translate into my world rather than swapping nouns. If the title only works when you keep one of their specific words, say the format does not transfer. Then write the thumbnail concept for the one you would pick. If you cannot describe a thumbnail for it, tell me the idea is not good enough yet.
If this happens, do this
Every one of these has happened to me or to someone I set this up for.
| Failure | Fix |
|---|---|
| Report ranked by views | Rank by score, with views and the median beside it |
| Shorts mixed into the baseline | Filter on lengthSeconds, or use the separate shorts array |
| A median computed over 2 uploads | Refuse under 10 long-form uploads. The script exits instead |
| You copied a 4-year-old outlier and it went nowhere | Bound the window to 12 months, or check the topic is still moving |
| You trusted the multiple a tool printed | Everyone sees that score. Compute your own over a stated window |
| A gaming format flopped in a clinic feed, and you blamed the method | Sort universal from niche-native first |
| Nouns swapped, title still theirs | Translate into your world. If one of their words survived, you copied |
| The watchlist never got rescanned | Put it on a schedule. It only compounds if it runs |
The tools I use for this
| Tool | What it is for here | |
|---|---|---|
| Scrape Creators | The research API this page uses. Search with view counts, plus a channel's uploads with Shorts separated. Both endpoints tested. | Docs |
| gstack browse | A free fallback with no API key. chain for multi-step jobs, snapshot -D to diff a channel's uploads page against last week. | Repo |
| Outlier research skill | The public skill this page runs. Read it, do not rewrite it. | Read it |
| Claude | Runs the scan, computes the medians, names the pattern, drafts the three remixes. | Open |
| NotebookLM | Where the top ten's transcripts go when you want the first spoken lines compared. | Open |
What I would tell you over coffee
- Look at a channel's underperformers too. The gap between a 12x and a 0.3x on the same channel, same person, same production, is almost always the packaging.
- Scan a channel you admire and find nothing above 2x? That's normal. Look somewhere smaller.
The free skill
The research routine I run before picking a topic. It searches 3 phrasings, computes views over the channel's long-form median, tiers and recency-checks the results, sorts universal from niche-native, drafts 3 remixes of the best one, saves by video id, and proposes a watchlist.
---
name: outlier-channels
description: Finds the YouTube videos in a niche that beat their own channel's normal. Scores each as views divided by the channel's long-form median, tiers and recency-checks them, reads the winners' packaging, sorts universal from niche-native, drafts horizontal, parallel and vertical remixes, saves everything by video id so no topic is researched twice, and proposes a watchlist. Uses real numbers from a research API; never estimates. Trigger on "find outliers about", "what is working in my niche", "research this topic on YouTube", "rescan the watchlist".
---

# Outlier Channels

Raw views measure audience size. Views divided by that channel's own median measure the topic. You're building a scored library of outliers and a watchlist that keeps scoring.

The full public skill lives at https://marketing.doctorleadflow.com/library/outlier-research/ and the free repo at github.com/drleadflow/thumbnail-system-starter. This file is the operating version.

## Before you start
- You need real view counts and channel uploads from a research tool: Scrape Creators or equivalent, the starter repo, or JSON the user fetched with curl. The API key stays in an environment variable, sent as a header. Manual fallback: the user pastes 10 to 20 video URLs with views and channel names.
- Never estimate views or medians. If a channel's uploads can't be fetched, score = unknown.
- Read the library first. If the topic was scanned before, list what exists with scores and dates, and only fetch what's new.

## 1. Search 3 ways
Literal topic. Outcome phrasing ("how I", "that worked"). Beginner phrasing ("for beginners", "explained"). Collect 30 to 60 candidates: title, channel, channel id, views, publish date, length.

## 2. Baseline per channel
For every channel, pull recent uploads, discard anything under 90 seconds (and any Shorts), and take the MEDIAN views of the 15 most recent long-form uploads. Median, never mean. If fewer than 10 long-form uploads come back, mark that channel's scores unknown and say so. Print the long-form count behind every median. Cache each median for 6 hours.

## 3. Score, tier, check recency
    outlier = video views / channel median
- 10x and up: the topic is doing the work. Study packaging and hook.
- 3 to 10x: good topic plus good execution.
- 0.5 to 3x: the channel's audience, not the topic. Format lessons only.
- Below 0.5x: underperformed even for them. Note why.

Flag anything published more than 12 months ago as a recency risk, not an opportunity. Show the top 15 by score with views, score and channel median side by side.

## 4. Read the winners
For the top 10: title construction, thumbnail concept (face, text, object, contrast), length, first spoken line if a transcript exists. For each, answer: what did they do differently that set it apart from the rest of that channel? Then name the shared pattern in 2 sentences. The pattern is the deliverable.

## 5. Sort portability
Label each of the top 10 UNIVERSAL (the structure works in any niche once the subject is stripped out) or NICHE-NATIVE (it works because of the subject). If the user sells a service, also flag whether the topic reaches someone who could buy.

## 6. Remix the best universal winner
For the user's topic and one person, write:
1. HORIZONTAL: one step sideways. Same shape, different scale or angle.
2. PARALLEL: the same idea, fewer words, smaller promise.
3. VERTICAL: one step higher. Add a stake, number or outcome, and say what credibility it needs.

Translate into their world rather than swapping nouns. If a title only works with one of the original's words, say the format doesn't transfer. Write a thumbnail concept for the pick. No thumbnail, no idea.

## 7. Save
Write every candidate to the store keyed by video id: topic, score, channel median, date, portability label.

## 8. Watchlist
Propose the 5 to 10 channels behind the outliers. On rescan: pull recent uploads, recompute the long-form median, score, surface anything above 3x with a line on what it did differently. "Nothing above 3x" is a finding.

## Rules
- Steal mechanics, never words.
- Both numbers, always, side by side.
- Never invent a number. A missing field is reported as missing.
- Report what the data says even when it's boring.
Want the research library already built and refreshing itself?
Inside the AI CEO Lab the Research to Content Engine module runs this on your niche, with the watchlist wired to your content calendar.