 AI CEO Lab
Instagram Competitor Analysis: Find Which Posts Worked for Any Account
Score every post against its own account's median, so you see what worked instead of who's bigger. Three tiers, cheapest first: free in the Instagram app, free in a spreadsheet, then a scraper with transcripts.
Most competitor analysis compares accounts to each other: followers, engagement rate, a SWOT tab. None of it tells you if a post did well. 40,000 plays is a flop on one account and a record on another.
The fix is one division: take an account's median plays, then divide each post by it. That works in the Instagram app, in a spreadsheet, and at 422 rows with transcripts, the size of my own pull.
This is for anyone who posts on Instagram and wants a swipe file they can trust. The same division works on YouTube, covered in finding outlier videos. One warning first: copy the big players and you inherit hooks that only work because their audience already knows them.
The mental model
Compare accounts to each other with follower counts and engagement rate, then copy the biggest account in your niche.
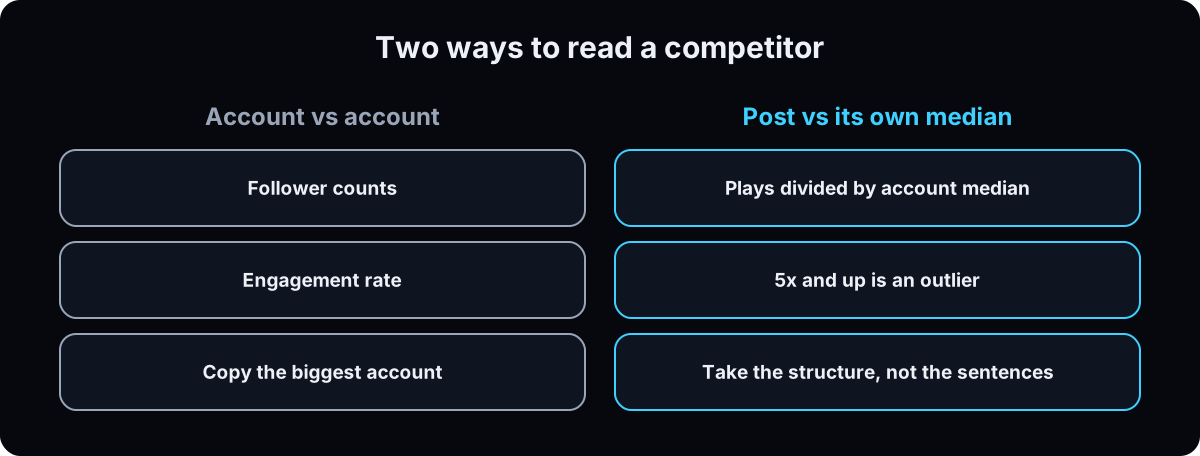 Compare every post to its own account's median. Use winners from accounts whose normal is close to yours, and take the structure, never the sentences.
| Term | What it means |
|---|---|
| Baseline | That account's median plays. Median, because one viral post drags an average up and hides every other winner. |
| Ratio | Plays divided by the baseline. 5x and up is an outlier. 1.5x to 5x is above baseline. |
| Mechanic | The structural move a post makes: job killer, free alternative, curated number, contrarian. One tag per post. |
Is this copying, and can it backfire?
I'm reading other people's posts to decide what to post. How is that not stealing, and what stops me turning into a worse version of an account I don't even like?
Both risks are real.
- You take the structure, not the sentences. Break a myth, give a shortcut, kill the objection, ask for a DM. That skeleton belongs to nobody. If a phrase survives your rewrite, you copied.
- Clinicians: some mechanics are closed to you. Job killer, leaked secret and urgency read as a claim when a doctor says them. A comment-gated lead magnet on a health promise is a regulated claim in a costume. Curated number, hidden feature and story transfer cleanly.
- Copying big accounts backfires. Their hooks lean on an audience that already knows them, so they land flat on cold viewers. Track small accounts, 2 of them outside your niche.
Scraping pulls public data under the platform's terms, so never point it at private content. And the honest limit: this shows what worked for someone else, not what will work for you. If every winner is a mechanic you won't run, find different accounts.
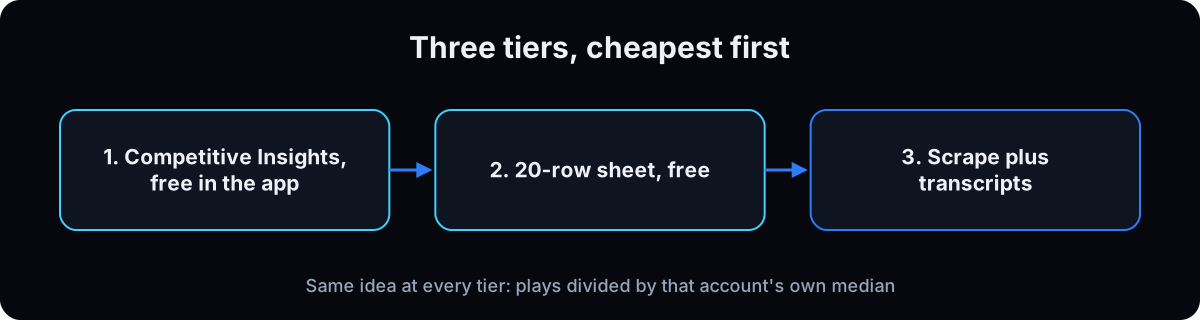
Three tiers, cheapest first
1. Choose the accounts, and choose small ones
The hardest part. Ask your audience with a story sticker which accounts they follow, tap Instagram's similar-accounts button, and search the words your buyer would type. Keep 5 in your niche and 2 outside it, all small and fast-growing.
Why: the explore algorithm pushes up-and-comers to cold audiences, and that's the audience you want.
2. Tier 1: open Competitive Insights (free, in the app)
 In your professional dashboard, open Competitive Insights. It tracks up to 10 public accounts over 3 months: posting volume, format split, follower growth and per-post engagement (Social Media Today covered the launch).
The best part is competitors' trial reels, the posts they're testing. Look for reels that appear twice or have an oddly low view count. No scraper returns this.
No button? You don't have the rollout yet, so go to tier 2. (Detail from heyDominik's walkthrough. App menus change, so check your own.)
3. Tier 2: 20 rows and one division
This is the whole idea. One row per post, 20 per account: account, permalink, plays, first caption line, length in seconds, and whether it ends with a comment keyword. Add a median per account, a ratio per post, and sort by ratio.
Use MEDIAN, never AVERAGE. One 100x post lifts the mean so far that every other winner scores below 1. Paid benchmarking tools report averages.
Rather paste rows into ChatGPT or Claude? Use the sheet prompt below.
account_median  =MEDIAN(FILTER($C$2:$C, $A$2:$A = A2))
post_ratio      =C2 / D2

# A account   B permalink   C plays   D account_median   E ratio
# then Data > Sort range > E descending
# never AVERAGE here: one 100x post buries every other winner
4. Read the top 20 and write one paragraph
For the top 20 by ratio, note the share ending with a comment keyword, the dominant format, the median length, and the repeating mechanic.
Mine, from the 422 posts in my own pull: 16 of the top 30 (53%) end with a comment keyword, the trigger behind comment to DM automation. Median length is 52 seconds, range 8 to 170, and only 12 of 30 fall in the 45 to 75 second band people quote, so length predicts little. 23 posts beat 5x and 105 beat 1.5x: expect about 5% real outliers. Recompute before you quote: my keyword share went from 77% to 53% when I ran the count.
python3 - <<'EOF'
import json, re, statistics as st
posts = json.load(open('posts.json'))
top = sorted(posts, key=lambda p: p.get('outlier_ratio') or 0, reverse=True)[:30]
kw = re.compile(r'\b(comment|drop|type|dm)\b\s+(the\s+word\s+)?\W{0,2}[A-Za-z]{3,15}', re.I)
n = sum(1 for p in top if kw.search(p.get('caption') or ''))
d = [p['duration_sec'] for p in top if p.get('duration_sec')]
print(f'comment keyword: {n}/30')
print(f'length: median {st.median(d):.0f}s, range {min(d):.0f}-{max(d):.0f}s')
print(f'in the 45-75s band: {sum(1 for x in d if 45 <= x <= 75)}/30')
EOF

# on my 422-post file this prints 16/30, median 52s (8-170s), 12/30 in band
5. Tier 3: scrape it when 10 accounts and 3 months run out
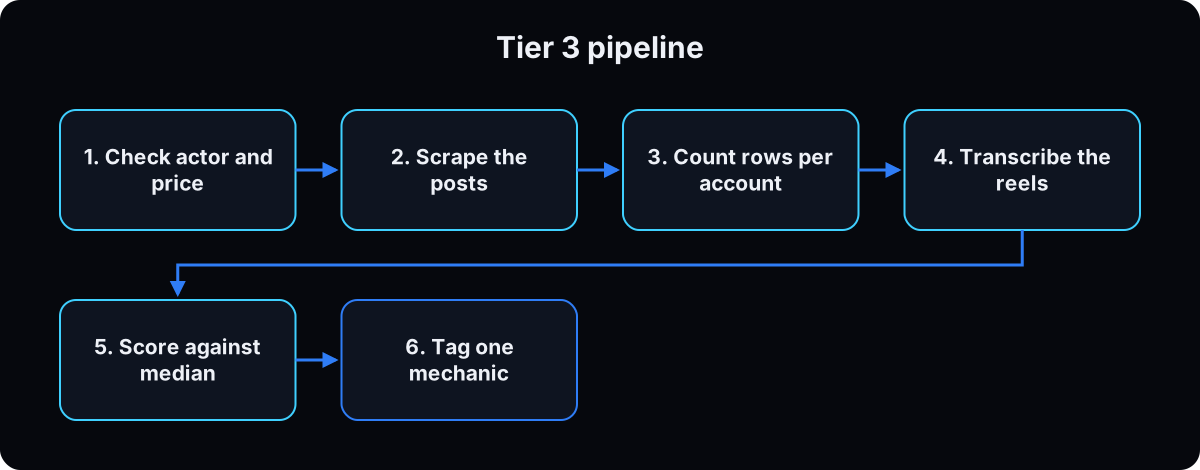 Apify's Instagram scraper takes profile URLs and returns plays, likes, comments, caption, timestamp, product type and video URL. Check the actor and price first. When I checked on 8 September 2026, the actor page read $0.0027 per result on the free tier, so my 9 accounts at 60 posts cost about $1.46. (
apify~instagram-post-scraper is the per-post version.)
Send the token as a header from an environment variable. Apify's API docs accept either, and the query parameter leaks into shell history and proxy logs.
In Claude Code, add Apify's MCP server (a connector that lets Claude run the scraper) and run /mcp to sign in, as Claude Code's MCP docs describe. In ChatGPT, run the scrape in the Apify console and upload the JSON.
# verify the actor and today's price before spending anything
curl -s https://api.apify.com/v2/acts/apify~instagram-scraper \
  | python3 -c "import sys,json;d=json.load(sys.stdin)['data'];print(d['username'],d['name']);print(d['pricingInfos'][-1]['pricingModel'])"

export APIFY_TOKEN=...   # env only, never in a chat
cat > input.json <<'J'
{"directUrls": ["https://www.instagram.com/handle1/", "https://www.instagram.com/handle2/"],
 "resultsType": "posts", "resultsLimit": 60}
J
curl -s -X POST https://api.apify.com/v2/acts/apify~instagram-scraper/run-sync-get-dataset-items \
  -H "Authorization: Bearer $APIFY_TOKEN" \
  -H 'Content-Type: application/json' -d @input.json > posts.json

# Claude Code only
claude mcp add --transport http apify https://mcp.apify.com
export DEEPGRAM_API_KEY=...   # transcription, env only
6. Count rows per account before you trust a median
This cost me a week. In my own scrape, 7 of 9 accounts returned 60 posts and 2 returned exactly 1. A 1-row account's median equals its only post, so its outliers vanish and nothing errors.
Count every time, drop or rescrape short accounts, and make any agent show you the count first.
python3 - <<'EOF'
import json, collections
posts = json.load(open('posts.json'))
for creator, n in collections.Counter(p['creator'] for p in posts).items():
    flag = '  <-- partial, do not trust its median' if n < 20 else ''
    print(f'{creator:24s} {n:4d}{flag}')
EOF
7. Transcribe the reels so you can read the hook
The caption holds the call to action. The transcript holds the hook. Send each video URL to a transcription API such as Deepgram's pre-recorded audio endpoint and store the text with the post. Reading hooks this way pairs with writing hooks for reels.
Expect gaps: 349 of 422 posts came back with a transcript in my pull, since 26 were carousels and some videos were unreachable.
8. Tag one mechanic per post, most specific rule first
A keyword rule list reads caption plus transcript and assigns one tag: job killer, free alternative, dashboard reveal, hidden feature, curated number, contrarian, absurd analogy, leaked secret, urgency, platform tactics, story, other.
Order matters: first match wins, so put the most specific rules first and other last.
Why: you can filter to one mechanic and read 6 transcripts back to back.
9. Remix one post, all the way, on paper
Do this once before you build anything else.
Their post (property): you don't need cash to buy the land, then get a loan to build the house. That's a misconception. You can get one loan for the land and the construction together.
The structure: break a myth, give one shortcut, kill the objection, end on a DM ask, no face in the first frame.
My version: you don't need to post every day to grow. That's a misconception. You grow faster posting less and tracking smaller creators' outliers instead of copying the big ones.
Same skeleton, no shared sentence.
Starter prompts
Paste these as written. They are short on purpose, because the long ones drift.
I am going to paste 20 rows per account for these accounts: [handle1, handle2, ...]. Each row is: account, permalink, plays, first line of caption, length in seconds. For each account compute the MEDIAN plays. For each post compute ratio = plays / that account's median. Sort everything by ratio descending. Then tell me, for the top 20 overall: 1) what share ends with a comment keyword 2) the dominant format 3) the median length in seconds and the full range 4) the one structural mechanic that repeats Use median, never mean. If an account has fewer than 10 rows, say so and exclude it rather than reporting a median for it. Never give me a number you cannot point at in the rows I pasted.
Here is a post from the dashboard: caption [caption], transcript [transcript], ratio [Nx]. First, name its structure in one line as a sequence of moves, not a summary. Then write my version of that same structure about [my topic] for [my one person]. Short lines, plain words, no statistics I have not given you, and no phrase carried over from theirs. Give me three first lines and pick one. If you cannot rewrite it without reusing one of their sentences, tell me the mechanic does not transfer instead of forcing it.
If this happens, do this
Every one of these has happened to me or to someone I set this up for.
| Failure | Fix |
|---|---|
| You sorted by plays and learned who has the biggest audience | Sort by ratio to the account's own median, calculated with MEDIAN, never an average |
| 2 accounts returned 1 post instead of 60 and nothing errored | Count rows per account first. Drop or rescrape anything under 20 |
| You tracked the biggest names in the niche | Track small, fast-growing accounts whose normal is near yours |
| Every tag came back as one mechanic | First match wins. Order rules most specific first, other last |
| You pasted the token into a chat or a URL | Environment variable, passed as a header. Rotate the one you pasted |
The tools I use for this
| Tool | What it is for here | |
|---|---|---|
| Instagram Competitive Insights | Free in the professional dashboard. 10 accounts, 3 months, plus their trial reels. Still rolling out. | no link needed |
| A spreadsheet | Tier 2 in full. One MEDIAN per account, one division per post. | no link needed |
| Apify | Runs the Instagram scraper. $0.0027 per result on the free tier when checked on 8 Sep 2026. | Actor |
| Deepgram | Transcribes the reels so you can read the hook without watching. | Docs |
| Claude | Runs the pipeline, writes the page and drafts the remixes. | Open |
| Blotato | Schedules the remixed posts. | Get it |
What I would tell you over coffee
- Do tier 2 with 20 rows before you touch a scraper. If a sheet doesn't change what you post, 422 rows won't either.
- Each week, look at the last 30 days for your 7 accounts, 30 minutes on a Monday. Rank spikes by shares over likes: a utility share, the post people send to someone, brings leads rather than applause.
The free skill
The tier 3 build, written for an agent. It scrapes your accounts through Apify, checks row counts, transcribes the reels, scores each post against its account's median, tags one mechanic, writes a private filterable page, and reports the patterns worth remixing in your voice.
---
name: instagram-remix-dashboard
description: Builds a private Instagram competitor swipe file. Scrapes the last 60 posts per account through Apify, checks row counts, transcribes the reels, scores each post against its own account's median plays, tags one hook mechanic, writes one static HTML page with filters and a transcript modal, and reports the patterns worth remixing in the user's voice. Trigger on "build my remix dashboard", "scrape my competitors", "what are my competitors' best posts", "refresh the creator vault".
---

# Instagram Remix Dashboard

Build a scored, transcribed, filterable swipe file. Plays alone measure an account's audience. Plays divided by that account's median measure the post. The user remixes mechanics, never words.

## Before you start
- Accounts: 9 to 15 handles. Prefer small, fast-growing accounts whose normal is close to the user's. Ask if none are given.
- APIFY_TOKEN and a transcription key must be in the environment. If either is missing, stop and say where to set it. Never accept a token in chat. If one was pasted, tell the user to rotate it.
- A place for rows keyed by post id (a table or a JSON file), so reruns append and never duplicate.

## 1. Scrape
Actor: apify/instagram-scraper. Pass the token as an Authorization Bearer header, never in the URL. Input: directUrls = profile URLs, resultsType = posts, resultsLimit = 60. On refresh add onlyPostsNewerThan = last scrape date.
Keep per item: id, shortCode, url, productType, timestamp, videoPlayCount, likesCount, commentsCount, shares if available, caption, videoUrl, displayUrl.
Save the dataset to a file and process it with a script. Don't read a large dataset into the conversation.

## 2. Count rows
Print the row count per account before anything else. If any account returned fewer than 20 rows, stop and tell the user. A short account's median is meaningless and nothing errors.

## 3. Transcribe
Send every item with a videoUrl to the transcription API and store the text with the post. Report how many came back. Missing transcripts are reported, never invented.

## 4. Score
Per account: median of videoPlayCount (median, never mean). Per post: ratio = videoPlayCount / account median. Badges: 5x and up = outlier, 1.5 to 5x = above baseline, else baseline.

## 5. Tag one hook mechanic
From caption plus transcript, assign exactly one, checking the most specific rule first and `other` last:
job killer, free alternative, dashboard reveal, hidden feature, curated number, contrarian, absurd analogy, leaked secret, urgency, platform tactics, story, other.
Keyword rules are fine for a first pass. Say the tags are rule based.

## 6. Write the page
One static HTML file with `<meta name="robots" content="noindex, nofollow">`, data baked in, no client-side API calls, no login:
- spotlight row: each creator's highest ratio post
- cards: thumbnail, handle, tag, plays, comments, ratio badge, caption excerpt, permalink
- filters: creator, tag. Sort: ratio, comments, plays
- modal: full caption, transcript, permalink

## 7. Report
1. Per creator: rows, median plays, median comments, transcript count, top posts by ratio with both numbers.
2. How many posts beat 5x and how many beat 1.5x.
3. Of the top 20 by ratio: share ending with a comment keyword, dominant format (screen recording, green screen, talking head, carousel), median length and full range.
4. The 3 mechanics that repeat, with 2 example posts each.
5. 5 remix angles: mechanic named, the user's topic, their one person, short plain lines, no stats, no borrowed sentence.

## Rules
- Never invent a number. A missing field is reported as missing.
- Mechanics are shared. Sentences are theirs.
- If the user is a clinician, flag job killer, leaked secret and urgency remixes as likely claims.
- Refresh appends by post id and recomputes medians with the new posts included.
Want the dashboard built on your niche with the remix scripts written?
Inside the AI CEO Lab the Research to Content Engine module runs this scrape on your competitors and turns the top ten into scripts in your voice.